





How Circle K accelerated DevOps incident triage to under 15 minutes with Amazon Bedrock
Circle K's DevOps team cut incident triage from 45-60 minutes to under 15 by building an agentic triage system on Amazon Bedrock. This post walks through the architecture, the initial Amazon Bedrock Flows implementation, the migration to Amazon Bedrock AgentCore, and the lessons learned from scaling it.
This post was co-written with Marek Klatowicz, Cloud DevOps Engineer at Circle K.
Many DevOps teams know the incident triage pattern: An alert fires, and before anyone can fix the problem, an engineer spends 45–60 minutes figuring out what happened. They pull logs, check service health, and correlate symptoms across a handful of tools. All of this happens before remediation can begin.
At Circle K, this challenge scaled with the business. The company operates more than 17,200 convenience and fuel retail stores across 27 countries. Behind the storefronts, a cloud-native infrastructure supports point-of-sale systems, loyalty applications, and electric vehicle (EV) charging applications running on AWS. As the company expanded its digital operations, the triage overhead grew with it. More services meant more alerts, and each one required the same manual investigation before remediation could begin.
To address it, Circle K built an automated triage system using Amazon Bedrock, a fully managed service that makes foundation models (FMs) available through a single API. For model availability by AWS Region, refer to Supported models by AWS Region in Amazon Bedrock. The system uses an agentic AI architecture to investigate each incident autonomously and deliver a structured summary to Slack within minutes of an alert firing. Instead of raw alerts, on-call engineers now receive actionable context, so they can act immediately rather than spending an hour figuring out what happened.
Since deploying this system, Circle K has reduced mean triage time to under 15 minutes, a 67–75 percent reduction based on the team’s internal incident-response metrics.
In this post, we describe the architecture for both the initial Amazon Bedrock Flows implementation and the migration to Amazon Bedrock AgentCore, and share lessons learned from scaling the system.
The challenge of triage overhead
Circle K’s DevOps team monitors infrastructure across multiple AWS accounts using Grafana. A typical day brings alerts for container restarts, elevated error rates, latency spikes, and failed deployments. Each alert is a useful signal, but as the system expanded, the team wanted to help on-call engineers quickly see which signals needed attention, with the right context.
When an alert came in, the triage involved a familiar sequence of manual steps: reviewing recent logs in Amazon CloudWatch, examining application-level traces in Amazon OpenSearch Service, checking Amazon Elastic Container Service (Amazon ECS) task status, and cross-referencing symptoms with internal runbooks in GitHub. This gave engineers the information they needed, but it also showed how much repetitive context gathering would be required as more services were onboarded.
The team recognized two areas where a proactive investment could help. First, the same log queries, health checks, and runbook lookups would be repeated for every incident. Second, the depth and speed of triage could vary with the on-call engineer’s familiarity with the affected service. As alert volume and service ownership grew, switching between multiple tools for each investigation could slow response and make it harder to apply the team’s best practices consistently.
Circle K’s DevOps team therefore started a research and development (R&D) initiative to explore how AI could support monitoring and incident triage. The goal was to automate repetitive context gathering and provide structured, actionable findings, while supporting engineers’ operational judgment during an investigation.
Why Circle K chose Amazon Bedrock
The team evaluated several approaches before building, including open source agent frameworks on self-managed infrastructure. That approach would have meant owning model hosting, prompt versioning, tool orchestration, and security controls.
With Amazon Bedrock, the team avoided that overhead. They could access foundation models through a single API and swap foundation models without rewriting code. Because Circle K already ran on AWS, Amazon Bedrock fit into existing AWS Identity and Access Management (IAM) policies, Amazon Virtual Private Cloud (Amazon VPC) configurations, and logging pipelines.
Two managed capabilities covered orchestration and retrieval. Amazon Bedrock helped with agent orchestration, giving the agents native tool use to call AWS APIs, query databases, and retrieve documents without custom orchestration code. Amazon Bedrock Knowledge Bases, the fully managed Retrieval Augmented Generation (RAG) capability, handled ingestion and retrieval of internal product cards, so the team did not need to run a separate vector database. This let the DevOps team focus on prompt design and tool definitions.
Data privacy completed the picture. Circle K’s incident data includes operational metrics, infrastructure details, and logs that can contain sensitive information. Amazon Bedrock does not share customer data with model providers or use it to train foundation models. For a team feeding production logs and internal service details into the system, this data handling approach met Circle K’s security requirements.
Solution overview
This section describes the initial architecture, which the team built on Amazon Bedrock Flows. A later section covers the migration to AgentCore.
The solution uses Amazon Bedrock Flows as the orchestration layer, coordinating a set of specialized agents that each handle a different part of the analysis. The pipeline starts when a Grafana alert publishes a notification to Amazon Simple Notification Service (Amazon SNS), which forwards it to an Amazon Simple Queue Service (Amazon SQS) queue. An AWS Lambda function polls the queue, extracts the alert payload, and invokes the Flow.
Inside the Flow, two agents are invoked in parallel. The AWSResourceExplorerAgent queries infrastructure across multiple workload accounts managed with AWS Organizations. It checks Amazon ECS task status, Application Load Balancer target health, and CloudWatch metrics and logs. At the same time, the OpenSearchExplorerAgent queries Amazon OpenSearch Service for application-level logs and distributed traces. This agent runs separately because OpenSearch returns large volumes of log data. Isolating it keeps each agent’s context window manageable. It also has exclusive access to the knowledge base, which contains product cards describing each service and its dependencies.
After both agents return their findings, the GitHubExplorerAgent runs. It receives output from the previous two agents and finds the affected service’s GitHub repositories. Then it searches their application code, infrastructure definitions, and recent commits to pinpoint the source of the problem and propose a concrete fix. Running it after the parallel agents means it knows exactly what to search for rather than performing a broad query.
All three outputs feed into an AnalysisPrompt node, which is a single model call with no tools attached. It receives the AWS resource data, the OpenSearch logs, and the GitHub context, then produces a structured summary: probable root cause, supporting evidence, affected service and owner, and recommended remediation steps. The prompt output uses a consistent format that the on-call team can scan in under 2 minutes.
The Flow returns this summary to the invoking Lambda function, which posts it to a Slack channel. The entire process from alert to Slack message takes 5–15 minutes depending on incident complexity.
The following diagram shows this architecture end to end, from the initial Grafana alert to the final Slack summary.

Figure 1: Circle K automated incident triage architecture using Amazon Bedrock Flows
Example triage
A Grafana alert: HTTP 5xx error rate on a service exceeds 5% for 3 consecutive minutes.
The AWSResourceExplorerAgent checks ECS task health in the target account and finds the database connection pool exhausted, with the ECS service attempting restarts. The OpenSearchExplorerAgent returns application logs showing “connection refused” errors from the service to its backing PostgreSQL database. It also retrieves the product card for the affected service from the knowledge base, which documents its dependency on that database. The GitHubExplorerAgent searches the service’s repository and infrastructure files and finds the Amazon Relational Database Service (Amazon RDS) definition. It sees that the service opens a new database connection per request rather than reusing existing ones.
The AnalysisPrompt receives all three results. It correlates the timing with a scheduled marketing campaign that started 10 minutes before the alert. It combines that with the GitHubExplorerAgent’s finding to recommend a concrete code-level fix rather than a temporary patch.
The final Slack message reads:
Scaling to Amazon Bedrock AgentCore
The Amazon Bedrock Flows architecture worked well for months, and simple incidents were triaged in under 10 minutes. Over time, the volume of data and the context behind each investigation grew, even though the set of services stayed the same. Some incidents required longer-running analysis than a single Flow node could complete.
The team first optimized within the existing design by filtering logs more aggressively, shortening context windows, and splitting certain services into separate Flows. These steps helped, but log volumes and the knowledge base kept growing.
Amazon Bedrock AgentCore met this need. AgentCore is a platform to build, connect, and optimize AI agents at scale with any framework or model. For this workload, the key capability was AgentCore Runtime: The full investigation runs in a single session, so each step can take the time its data requires. AgentCore Runtime supports sessions of up to 8 hours, well beyond what the current investigations need. The team containerized their agent logic and deployed it on AgentCore Runtime.
The following diagram shows the production architecture after the move to Amazon Bedrock AgentCore.
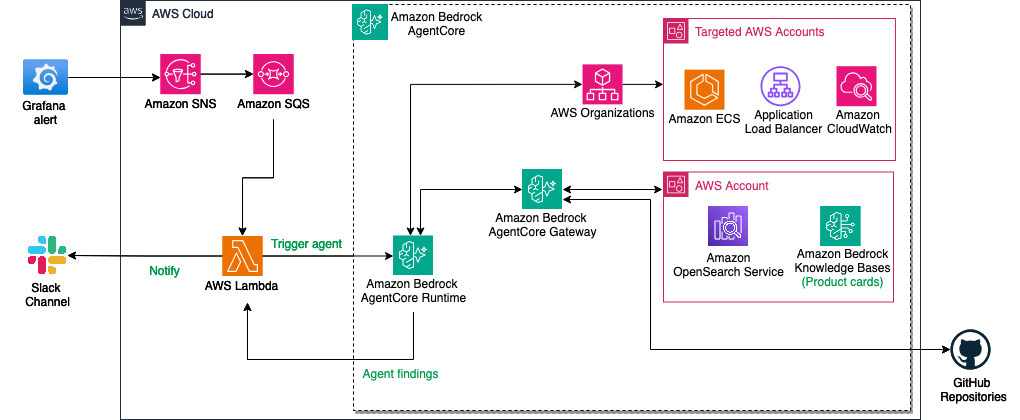
Figure 2: Production architecture using Amazon Bedrock AgentCore Runtime and AgentCore Gateway
The analysis logic stays the same, but the way it runs has changed. The three specialized agents from the Flows version are now consolidated into a single agent running in an AgentCore Runtime session. The Lambda function starts the session, and the agent performs the same steps as before. It queries AWS resources across accounts, pulls logs from Amazon OpenSearch Service, searches GitHub, and retrieves product cards from the knowledge base. The agent returns its findings to the Lambda function within 15 minutes, which is within the maximum Lambda timeout. The Lambda function then posts the structured summary to Slack.
Amazon Bedrock AgentCore Gateway, a capability of Amazon Bedrock AgentCore, brokers the agent’s access to its data sources, including Amazon OpenSearch Service, Amazon Bedrock Knowledge Bases, and GitHub. The Gateway exposes each source as a tool the agent invokes, which centralizes access control and makes it simpler for the team to add or change data sources.
How AgentCore Runtime supported the team’s growing scale
Beyond longer-running sessions, Amazon Bedrock AgentCore Runtime added three capabilities that supported the team’s growing scale: session persistence, OpenTelemetry-based observability, and framework flexibility.
Session persistence: The agent keeps an intermediate state throughout an investigation. If a first pass over the logs surfaces something, the agent can run a second, more targeted pass without losing the context it has already built. This fits the iterative way that complex, multi-service incidents are investigated.
Observability: AgentCore captures traces from each session using OpenTelemetry standards and surfaces through CloudWatch. The team can see how long each step takes, which knowledge base queries the agent makes, and where bottlenecks occur. These insights feed directly into prompt tuning.
Framework flexibility: With AgentCore Runtime, the team can deploy containerized agents built with a wide range of frameworks. They can iterate agent logic, add triage steps, or restructure the agent’s reasoning as their requirements change, all on the same Runtime.
The AgentCore architecture now runs in production and handles the full range of incidents, from simple single-service alerts to large multi-service investigations.
Results
Circle K deployed the AgentCore version of the triage system in April 2026. Based on the team’s internal incident-response metrics, mean triage time dropped from 45–60 minutes to under 15 minutes, a 67–75 percent reduction. Straightforward incidents receive a summary in 5–8 minutes. Complex multi-service incidents, which previously took more than an hour to triage manually, now complete within 15 minutes.
Engineers now start from a summary instead of gathering context themselves. The team sees three changes in how incidents are handled:
Consistent triage. Every on-call engineer receives the same structured summary, with the same log excerpts, knowledge base references, and recommended next steps, regardless of how well they know the affected service.
Faster escalation. When an issue requires support from another team, the summary gives the on-call engineer the relevant context for a timely, informed escalation.
Quicker handling of false alarms. When the analysis finds healthy services and no correlated errors, the engineer can acknowledge the alert and move on.
Lessons learned
Building this system took several iterations. Four lessons stood out that apply to teams building a similar solution with Amazon Bedrock.
Include log content directly in the prompt. Early versions passed only log group names and time ranges, then the agent attempted to query CloudWatch through action groups. This added latency and often returned too much data to process. Circle K got better results by having Lambda functions pre-query the logs and pass relevant lines directly to the agent. The agent reasons faster when it can read the actual error messages.
Tune retrieval and generation for use cases. Retrieval configuration significantly affected result quality from the knowledge base. After testing the available options, the Circle K team found that an Amazon Bedrock Knowledge Base with its default configuration worked best for their data. Amazon Bedrock handles embeddings, indexing, and vector storage end to end, so the team has fewer components to maintain. On the generation side, a well-designed system prompt and a tuned temperature setting produced consistent summaries in Slack.
Narrow the code search with findings from the logs. Searching for the service’s repositories without a lead returns too many results to be useful. The team runs the GitHub search after the AWS resource and log analysis, so the agent already knows which error, component, or recent change to look for. In the example triage, this is how the agent found that the service opened a new database connection for every request.
Keep the analysis logic independent of the orchestration layer. Analysis time grows with data volume, so plan for investigations to take longer over time. The team kept its prompts, tool definitions, and analysis steps separate from the flow structure. This made it possible to consolidate them into a single agent on AgentCore Runtime without rewriting the triage logic.
Next steps
Today, the triage system finds the probable root cause and recommends a fix, and an engineer carries out the fix. Next, the team plans to integrate with AWS DevOps Agent, so the system can also handle simple remediations. Examples include restarting a task, scaling up a service, or rolling back a deployment. An engineer will approve each action in Slack before it runs.
The team also plans to give the agent more context to work with:
- Jira, to link each incident to related tickets and track follow-up work.
- Confluence, to add internal documentation to the code and logs the agent already reads.
- Runbooks in the knowledge base, so the agent can match symptoms to known failure modes and fixes that worked before, instead of relying on product cards alone.
Conclusion
The Circle K team went from 45–60 minutes of manual incident triage to under 15 minutes by automating the context gathering that engineers used to do by hand. The system collects data from logs, AWS resources, and code, lets an agent reason over it, and delivers a structured summary to Slack.
The team built the first version on Amazon Bedrock Flows and Amazon Bedrock Knowledge Bases. As investigations grew larger, the team moved to a single agent on Amazon Bedrock AgentCore Runtime, with AgentCore Gateway providing access to its data sources.
If your team spends most of its incident response time gathering context rather than fixing problems, this pattern applies directly. To get started, explore Amazon Bedrock AgentCore and Amazon Bedrock Knowledge Bases. For hands-on guidance or to discuss your use case with an AWS specialist, visit the Amazon Bedrock getting started page or contact AWS.
We want to hear how you approach incident triage. Share your experience in the comments.
About the authors